
Voice and audio for the streaming era
On-device voice control, hybrid cloud-and-edge discovery, interactive watch and listen parties, and automotive integrations — purpose-built for music and video streaming platforms.
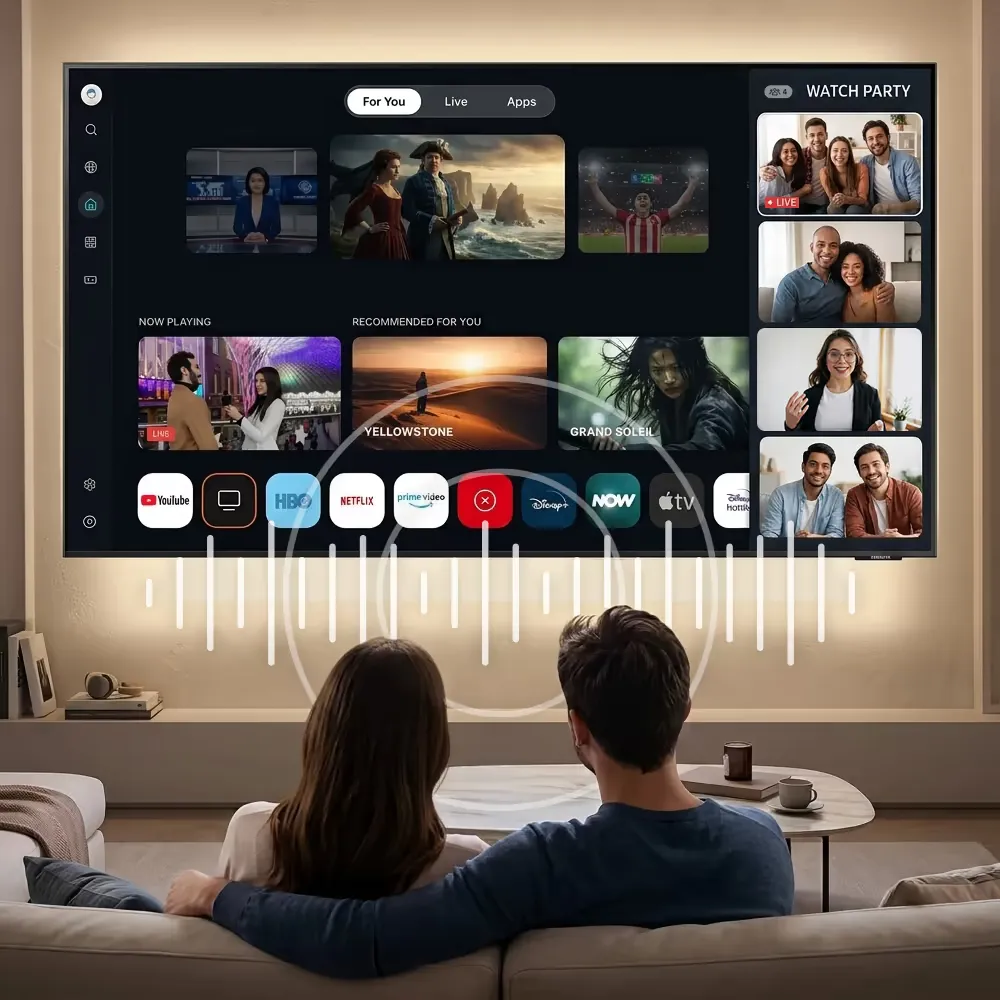
Built for
- Music services
- Video streamers
- Smart-TV platforms
- Connected radio
- Live-event companies
We work with teams shipping consumer streaming experiences at scale — across smart TVs, phones, in-car systems, wearables, and set-top boxes. We've shipped work for Amazon Music, Live Nation, LiveOne, and a top-5 US streaming platform, among others.
Where streaming teams move faster with us
Four areas where we consistently ship production work for streaming customers.
Hands-free control, fully on-device
Wake-word, intent recognition, and command execution that run entirely on the user's device — no round-trip, no cloud dependency, no per-request billing.
- Works offline. Voice control still responds in a basement, on a plane, or in a dead zone.
- No per-request cloud costs. Core control loop never touches a hosted LLM or ASR endpoint.
- Private by default. Audio stays on the device unless the product explicitly sends it elsewhere.
Voice-controlled playlist and content discovery
Bridge on-device voice technology with cloud-based LLMs — only when the request actually needs reasoning or catalog knowledge. Latency where it matters, cost where it doesn't.
- Edge handles the common path. "Pause," "next," "volume up," "play my morning mix" never leave the device.
- Cloud handles the hard path. "Build me a playlist of upbeat 90s hip-hop I haven't heard" routes to an LLM against your catalog.
- Cost- and latency-efficient by design. You pay for cloud inference only on queries that need it.
Watch parties, listen parties, and interactive games
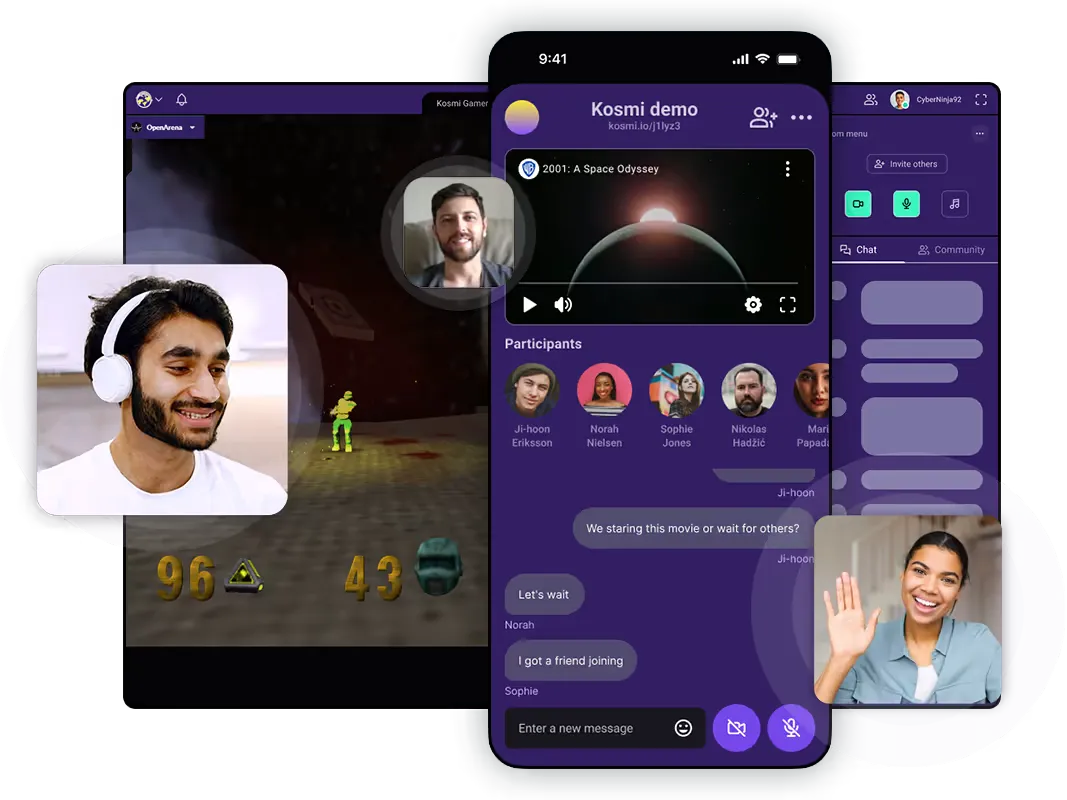
Synchronized playback, low-latency voice chat and interactive game layers — the stack behind Kosmi, our in-house watch-party platform used by millions.
- Frame-accurate playback sync across devices and networks.
- Spatial voice chat that ducks under the content stream.
- Pluggable game and reaction layers on top of your existing player.
Automotive integrations
Bring your streaming experience into the car with voice as the primary interface. Our Driving Buddy demo shows how on-device voice, music control, and conversational assistance behave in a real driving context.
- Low-latency wake-word and command recognition over road noise.
- Media-aware voice: ducks audio, resumes cleanly, handles interruptions.
- Integrations with CarPlay, Android Auto, and OEM head units.
A free SDK and runtime behind every build
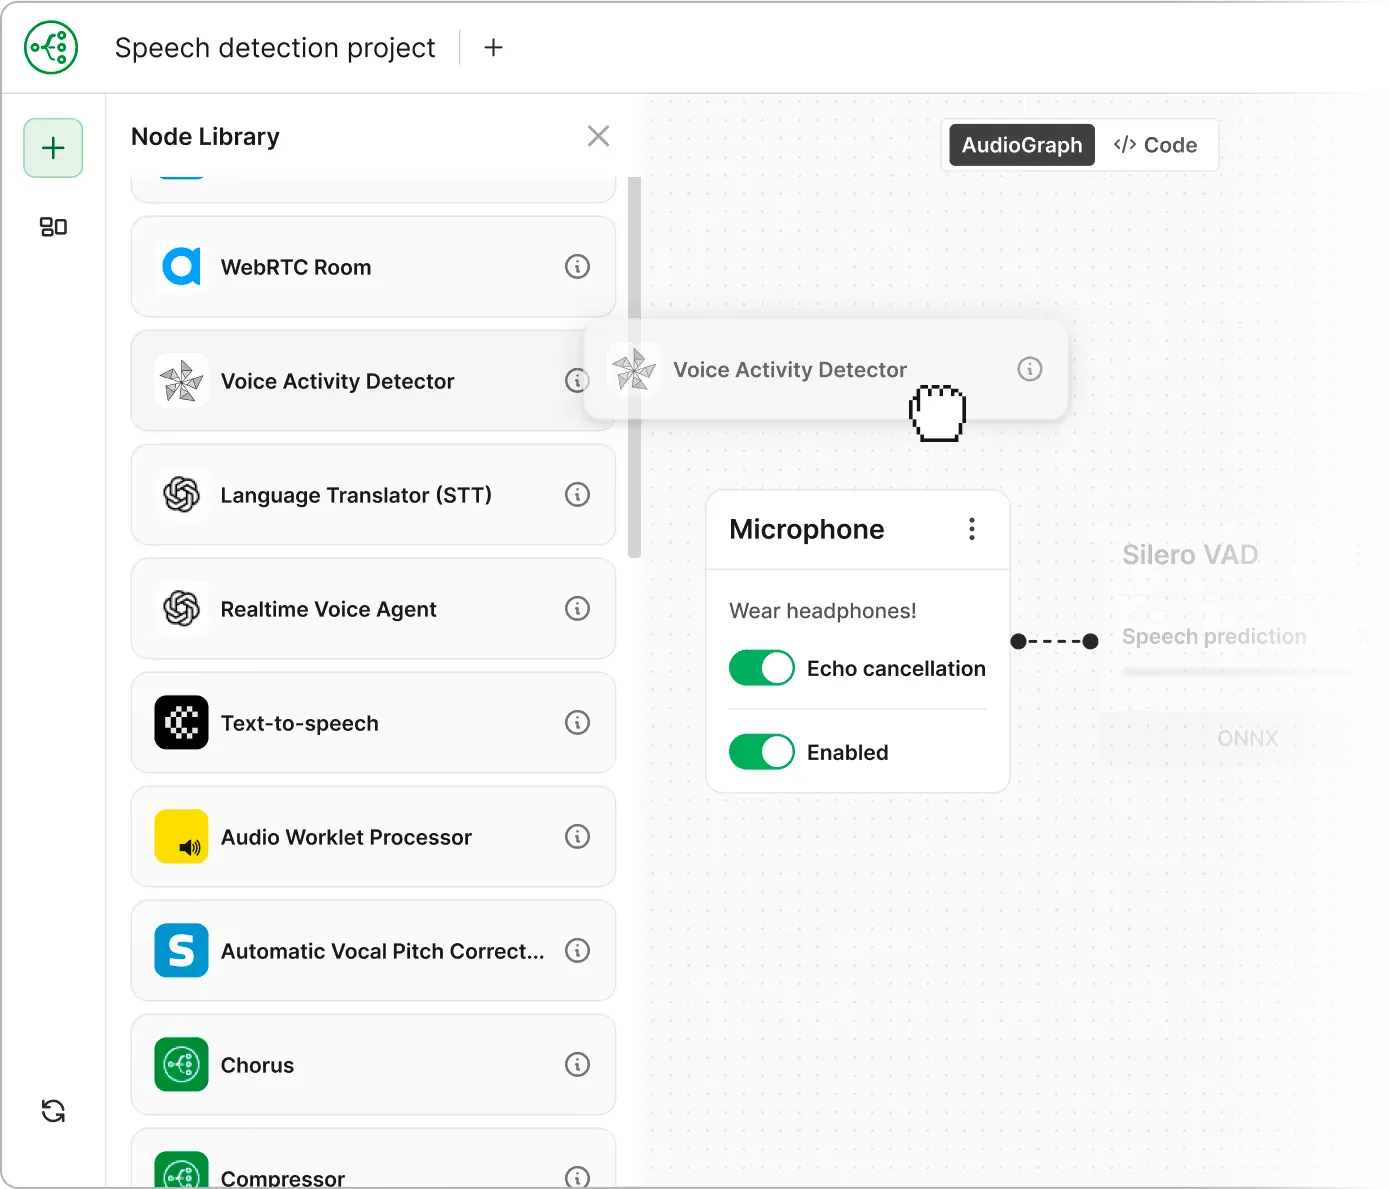
Switchboard is Synervoz's cross-platform audio SDK and runtime — a C++ core with higher-level bindings for iOS, Android, macOS, Windows, Linux, web, smart TVs, embedded and automotive. We use it on every engagement; so can your team.
- One audio graph, every platform. Reuse the same pipeline from your smart-TV app to your automotive integration.
- Node-based composition. Mix, duck, resample, encode, decode, run noise suppression, bridge voice services — plug nodes together like a hardware rack.
- Free SDK + Editor. Download it, prototype in the browser-based Editor, deploy via the SDK.
- Backed by our engineering team. Our consulting and build engagements extend the same SDK your team is using.
The parts most teams underestimate
Streaming-grade voice and audio looks straightforward from the outside. These are where real projects go sideways.
Echo cancellation during playback
The TV is speaking while the user is speaking. Doing voice control over your own content stream is a nontrivial AEC problem.
Wake-word on constrained hardware
A smart-TV SoC, a remote with a mic, or an embedded automotive head unit does not have a GPU. Model and runtime choices decide battery life, cost, and accuracy.
Latency budgets for interactive
Watch parties and voice-driven games have end-to-end budgets measured in tens of milliseconds. Casual approaches do not survive contact with real users.
DRM-adjacent audio paths
Pulling audio out of a protected content pipeline to run analysis or voice on top of it is a careful dance across platform APIs and content-protection rules.
Cross-platform parity
iOS, Android, Roku, Tizen, webOS, Android Auto, CarPlay, Linux embedded — the same feature behaves differently on each. Shipping once isn't shipping.
Hybrid cost control
Every roundtrip to a hosted LLM or ASR service is a line item at scale. Deciding which requests stay on-device is a product and architecture call, not just an ML one.
Keep exploring
Engagement model
Most streaming projects start with a short scoping phase, grow into an hourly engineering engagement, and often become long-running partnerships.
Phase 0 discovery
Uncover technical risks, define architecture, and map out a build timeline prior to a larger commitment.
Dedicated team
From ~0.5 FTE to multiple FTEs, billed hourly. Dedicated monthly engineering, staff augmentation, consulting and more.
Ongoing partnership
Streaming projects evolve. We stay with you through launch, iteration, and new platforms.
Ready to build the next streaming voice experience?
Tell us about your platform, your users, and where voice and audio need to show up. We'll come back with a technical read and a sensible path forward.